After a production incident, the first question in the retro is always some version of "how did this get through?" — and the honest answer is almost never "QA missed it."
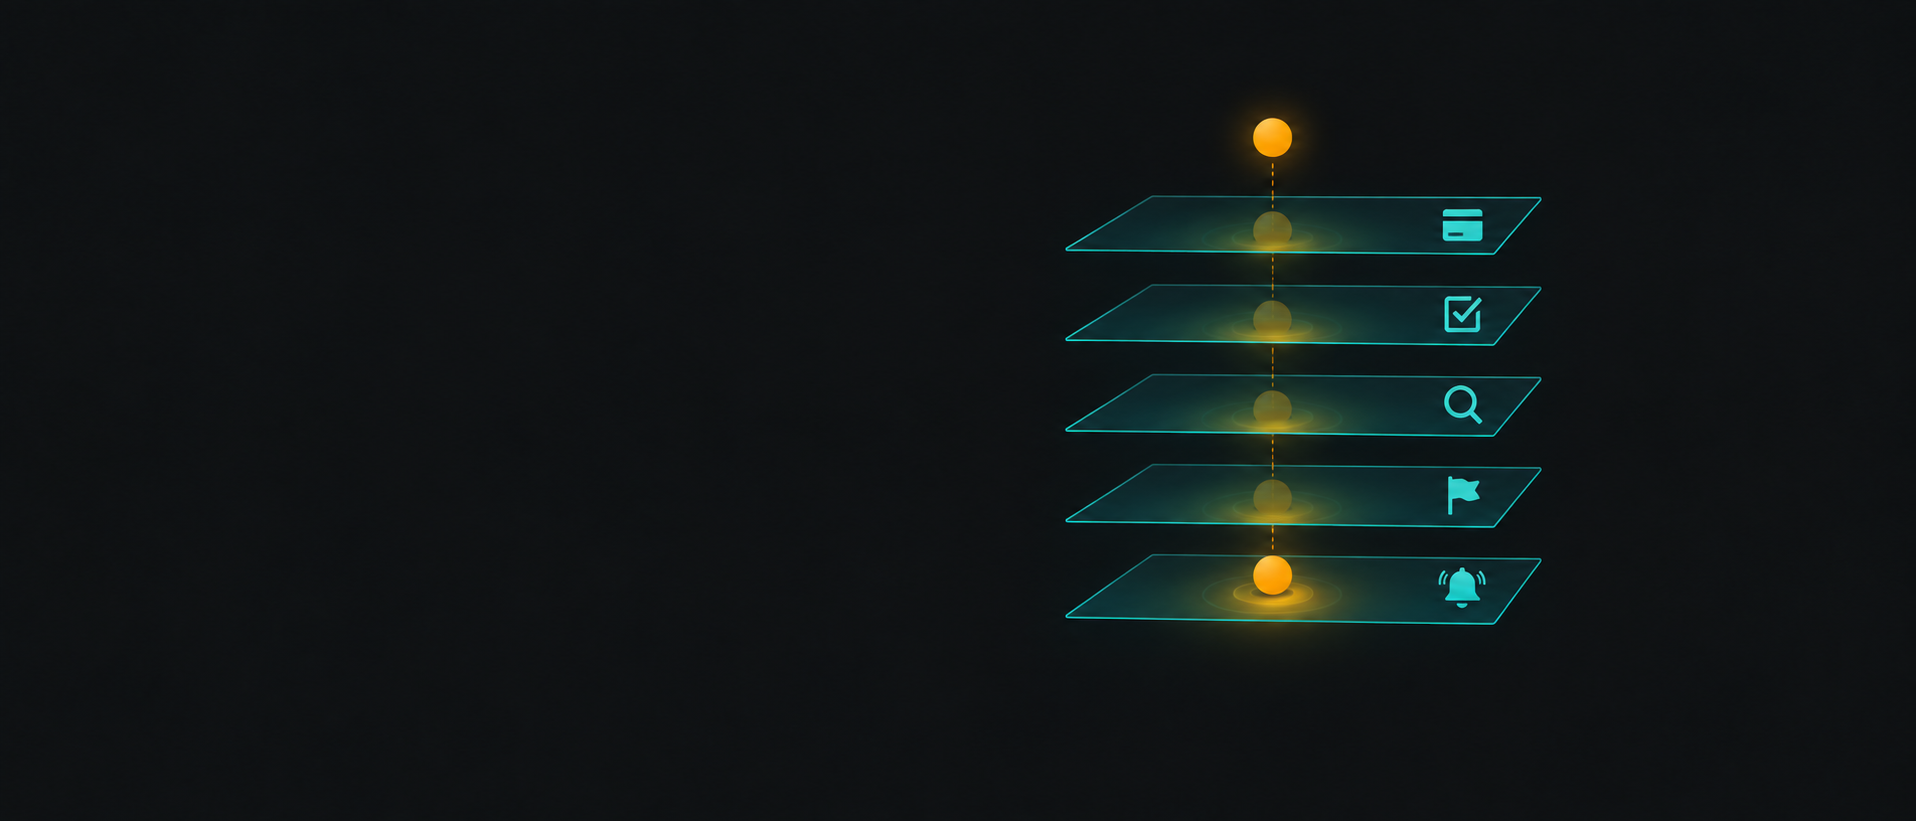
The incidents I've been adjacent to were each preventable at a different layer than the one that failed. The bug existed because the acceptance criteria were ambiguous. The review passed because the review checklist didn't cover that class of change. The QA pass was scoped to what was changed, not what was affected. The rollout had no flag to turn it off. Each layer had an owner. Quality still fell through — because it's a system property, not a person's job.
Individual versus system responsibility
Individual ownership is real: you own the code you ship. But a single developer's diligence cannot cover a gap that exists in the system — ambiguous requirements, no page-level visual regression, no staged rollout. When a team relies on heroics, quality becomes a lottery.
The healthier framing: every layer has an owner, and every owner has a mechanical backstop.
Risk-proportional verification
Not every change deserves the same scrutiny. The incident-informed default:
| Change type | Verification floor |
|---|---|
| Copy, styling on isolated components | Review + component tests |
| Shared component change | + page-level visual regression on consuming pages |
| Data/logic in a critical journey | + E2E on the journey, staged rollout |
| Auth, payments, data handling | + server-side checks confirmed, audit logging, canary |
Sizing verification to risk — instead of applying the same ritual everywhere — is what keeps the heavyweight checks affordable for the changes that genuinely need them.
The layers that caught things later
- Acceptance criteria: written as verifiable behavior, not vibes. "The form submits" has no failure mode; "submitting with an empty email shows the inline error and does not call the API" does.
- Review: checklists for what class of change it is — shared component? auth path? — not a general "LGTM."
- QA: scoped to affected surface (the blast radius), not just the diff.
- Page-level visual regression on the pages a shared component feeds. This one caught more near-misses than any other investment.
- Rollout controls: feature flags and staged rollout turn "we shipped a bug" into "we disabled a feature."
- Observability: alerting on the user-visible symptom, so the dashboard finds it before support tickets do.
Blameless learning versus accountability theatre
"Blameless" doesn't mean consequence-free — it means consequences attach to systems, reliably, instead of to people, dramatically. Accountability theatre looks like finding a name; blameless learning looks like leaving the retro with a layer that has a new owner and a mechanical check.
No incident-free team exists. Teams that own quality as a system have short incidents, few surprises, and no scapegoats.